


A team of 5 took a weekend prototype to an enterprise-grade product and deployed it to production in about 5 months, at roughly 5x the output per engineer of a comparable traditional build. This is the account of how that happened: what worked, what broke, and the way of working we landed on. It covers the multi-agent build, the failed jump to production, the human-first reset, and the lessons we would carry into the next project.
What does it take to take an AI-built prototype to production?
With ever-improving coding agents, vibe-coding a new idea has become easy, and the timeline for a hobby project or proof of concept has shrunk.
But we wanted to know what it takes to build at enterprise scale, where there are real consequences and thousands of users. Think sensitive data, strict role-based access, real audit requirements, and high stakes if we get it wrong.
What’s the best way to build that? It’s not vibe-coding and it’s not the traditional SDLC. It’s somewhere in between. We set out to find the answer and to figure out new ways of working along the way.
Chapter 1: How we built the prototype fast with multi-agent orchestration
The easy part was generating a working prototype from a spec using multiple agents. We started with the high-level PRD. Along with the tech stack and user journeys, it had the:
- Business rules
- Personas
- Access levels
- Types of access
- Functional requirements
- A data model
- Non-functional requirements like scalability
We knew we couldn’t run a single agent session to implement the whole PRD. The context window would be too small, and the agent would hallucinate halfway through. So we built a multi-agent orchestration:
- A planner agent to break down the PRD into work items
- A coder agent to do the work
- A separate reviewer agent to check it, with git plumbing
- A human in the loop to resolve agent conflicts
The agents needed a way to communicate on a shared message board to justify their actions, and any disagreement had to be escalated. We fed it the PRD and the acceptable mocking for real integrations, authentication, and persona derivation, then started the pipeline. The planner divided the PRD into work items, then the coder and reviewer went to work.
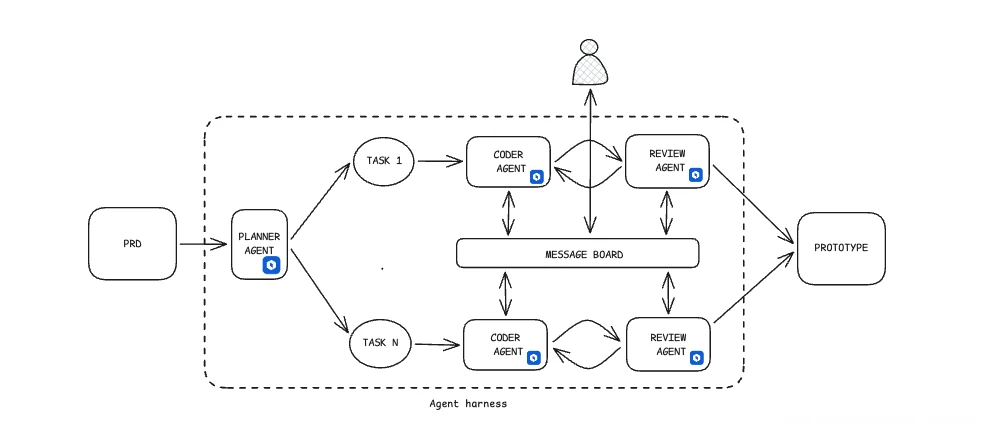
About 15 hours, ~250 agent sessions, 100+ review rejections, and 10+ escalations to a human later, a product was born. It wasn’t a wireframe or a mock. It was a running application with a real database that a user could actually use.
We had the prototype. Next step was to review the code feature by feature while replacing mock dependencies with real ones.
Chapter 2: Why the prototype broke on the way to production
The prototype already had the personas and rules defined, but they were mock-based. We wanted to keep the same access levels and business rules, and just swap in the real auth system. The product also leaned on upstream dependencies, both for foundational data and for access and permissions.
Before touching any of it, we added E2E tests. The idea was simple: lock in the current behavior so that as we replaced parts of the system with real integrations, we wouldn’t silently introduce regressions. In theory, this should work.
It didn’t. As we started integrating, the cracks showed:
- The real schema differed from the mock. The original DB schema didn’t hold, and we couldn’t just transform the data to fit it, because the prototype had baked in incorrect assumptions and a lot of shortcuts to reach the intended outcome.
- Foundational changes broke the E2E tests. Every PR came with E2E test changes, which defeated the whole point of having them. With our limited domain knowledge, we couldn’t tell right from wrong in review.
- The ground kept moving. New requirements landed from product, and the prototype’s some of the assumptions still needed fixing, all at once.
- We had no architecture to steer by. Without a high-level system design, we had no opinion on how things should be implemented. The code grew complex, agents kept linking domains in ways that felt wrong, and we hit cyclic dependencies again and again.
As we started going through the codebase, we began identifying architectural decisions that wouldn’t scale. We divided the codebase into what we can keep and deleted the rest. We understood code generation is not hard anymore. The agents could produce code faster than we could understand the domain, and no amount of generated code can fix a problem we don’t yet understand. The bottleneck is human context.
Chapter 3: How we fixed it by making the problem smaller
We made the problem small enough to understand, then worked out how to build from there. We took a step back. The last attempt failed because we were building faster than we could understand, so this time we made the problem smaller on purpose. We picked a single feature, something our team could actually digest and ship in a couple of weeks, and used it to work out how we should be building.
Iteration one: build one feature end to end
We took a smaller PRD and broke it into multiple tickets the team could execute in parallel. We planned the tickets before executing, making sure each one contained everything that was important to us. We reduced bad design decisions before they became code. Execution was easier to follow, one work item, one PR. We stayed closer to what the agents were actually building.
Now we started running into a different set of problems:
- Undesired product behavior showed up late. Even with complete tickets, our thin domain knowledge meant edge cases surfaced too late. The code matched our architectural vision but differed on product use cases. Product kept catching wrong behavior after merge to main, so we kept going back to fix it.
- Reviews started flagging real gaps too. Because major decisions were being made without the entire eng team involved, PR reviewers either struggled to understand the change or proposed different designs.
The problem was clear. We were still discovering the domain while the agent built it, not before. These have to shift left!
Iteration two: understand and plan first, then execute
Enterprise-grade differs from a vibe-coded product in that the person executing the spec isn’t the one shaping the product. Multiple stakeholders are. And an agent can’t stop mid-build to ask product, design, or compliance a question. So every decision that matters has to be settled up front and made explicit before the agent starts.
So before any agent touched the feature, we did the boring, traditional thing: real planning and grooming, up front, with no AI crutch. The team went through the feature, asked edge-case questions, and fully ingested the design.
Then we built an interactive planner with access to the codebase, the PRD, and other project artifacts. By design, it asked clarifying questions and surfaced gaps in the PRD. We conversed with it, and once every question was answered, we shaped the breakdown and refined the tickets before a line of code ran.
One problem remained: even when done right, the PRs were still large compared to traditional PRs. The PR review agent on Bitbucket had no issues reviewing the PR; however, we found it difficult to update our mental map of the code when the PR was large. So we built a PR review buddy. It has access to the codebase, the PRD, and the work item, and it can actually answer questions about the change. It doesn’t just flag gaps, a reviewer can use it to understand the code without pulling in the author for simple questions.
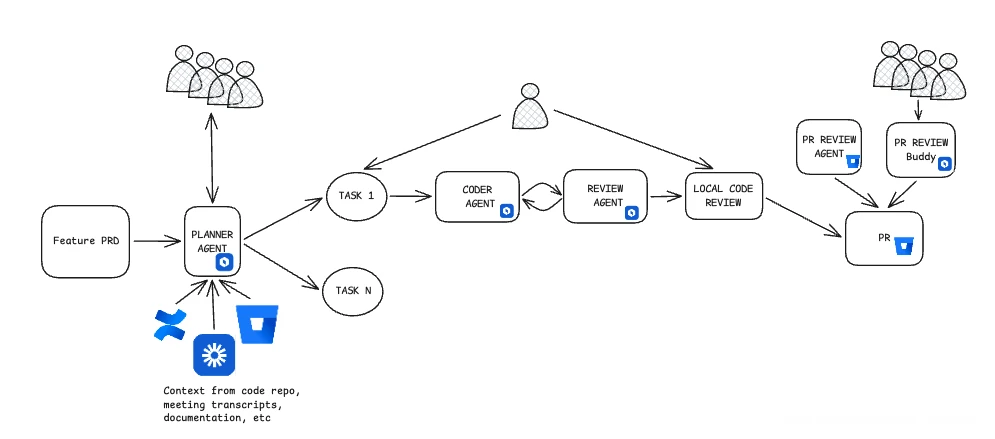
This was the turn! Because we now owned the domain before writing a line: Planning was faster, PR reviews were easier and execution accelerated!
Chapter 4: How we landed it in production and measured the result
We landed the product in production without any issues, and measured a roughly 5x gain against a real internal baseline. We worked this way for the next few months, and it stayed frictionless. Along the way we kept improving our tooling, building configurable workflows that let a human choose which parts to automate and when to step in and take control.
The result: a team of 5 took a weekend prototype to an enterprise-grade product and deployed it to production in about 5 months, at roughly 5x the output per engineer of a comparable traditional build! Not a demo, a real system with sensitive data, real auth, and audit, live for real users.
We didn’t estimate this. We ran it against a real internal baseline: a similar-class product on the same tech stack, shipped the old way by a traditional team two years earlier. Stacking a newborn product against a mature one proves nothing.
So we lined up equivalent phases instead, each product’s opening months from its first commit, and ran the same scripted measurements across both. First we confirmed the two were in the same weight class: comparable database schema size, a comparable external-integration surface, the same dominant languages, and a similar volume of hand-written code. Then we compared what it took to get there.
Chapter 5: What we learned building enterprise software with AI agents
The biggest lesson: humans still own the domain and the decisions, while agents accelerate execution. Planning, grooming, and reviewing with others still matter, and so does capturing what comes out of it. If a teammate would need it, the agent needs it too.
So we fed the team’s decisions into a long-term memory store: a note-taker agent for what was decided in meetings, and a chat agent to catch the important pivots buried in a thread. The more context the agents could reach, the better the artifacts they produced.
A few things we’d carry into the next project.
- We found it worked best when humans still made the calls. Agents accelerated execution; the architectural and product decisions, and a gate on anything risky, stayed with us.
- One-shotting a production app, or just “running loops” over it, didn’t work for us. The single line quietly holding the app together is exactly the one an agent will happily change. Agents felt like one-wish willows: they grant the wish, but the cost is hard to see unless you understand your own app.
- Owning the domain up front paid for itself. The time spent digesting the spec and enumerating edge cases before any agent ran is what made the fast part fast. Once the team knew the domain well enough to groom and review quickly, everything got easier.
- Treat agents as teammates. If a person on the team would need it, the agent needs it too. A convention or gotcha stuck in one engineer’s head is out of reach for an agent, forcing a human back into the loop. Written where the agents could query it, that knowledge paid off every time.
- Skills that teach agents to operate the app compounded. Anything a human does by hand is a candidate for a skill. Setting up a workspace, running test suites, connecting to a dev DB to debug, spinning up a mock integration, generating a UI component from the design: we captured each as a skill the agent could run unattended.
- A single agent trusts itself too much, so layered review matters. That trust means an agent can drift from its starting instructions. Pairing a separate review agent with our own manual review before asking anyone else caught a lot.
- Build the one-off tool. The bottleneck kept moving, and we tried to adapt. Expensive tooling meant we’d skip anything too specific to a single product. Not anymore. When a human bottleneck shows up, it’s now cheap and worthwhile to build a custom tool.
- Monorepo is not a bad idea. The agent doesn’t care that one side is one language and the other another. It cares about seeing a change end-to-end. With client, server, schema, migrations, and tests in one repo, it can trace the UI down to the database and see the full blast radius before touching anything.
Chapter 6: New ways of working
We pushed our ways of working to the extreme, then scaled back to a spot that fit. It wasn’t far from the existing agile SDLC. But AI agents let us speed up the phases: planning and reviewing stay human-heavy, while execution becomes AI-heavy with a human in the loop for reviewing and steering. The net effect on the SDLC is transformative.
Enterprise software is built by teams with different kinds of expertise, not by one person with a good prompt. Product, design, security, and the engineers all shape the work, and an agent can’t stop mid-build to ask them. So we can’t rush grooming and planning. The agent work needs to be reviewed diligently as well. At enterprise scale a wrong assumption is expensive. It might be an access rule, an audit trail, or the data model, and we don’t want to find out when real users run into it.
That’s where our Atlassian tools carried much of the load. Our decisions were scattered across the places we actually work. Confluence pages, Loom recordings of brainstorms, design decisions in Slack. Rovo could reach all of it through the Teamwork Graph and read it back when we were finalizing a PRD. From there the PRD broke down into Jira tickets, and those tickets became the execution loop for the agents. PRs went to Bitbucket, where a review agent inspected them first. Where our workflow needed something specific, we built our own agents on top of Rovo.
AI is reshaping how we build, but it hasn’t automated the SDLC end to end. We still need to be in charge and to leverage AI like any other tool we’ve had so far. Treating agents as experts at doing what they’re told, and giving them the context they need, can genuinely transform the timeline and the resources required to build a new product. And, just like before, embracing change and being willing to adapt helped us make a real impact.


