


There’s a concept in software engineering called a software factory – a structured, repeatable pipeline that takes raw inputs (requirements, code, tests) and reliably produces high-quality outputs (working software). The magic isn’t just automation. It’s the combination of standard tools, curated configuration, and encoded expertise that makes every run predictable, consistent, and improvable over time.
Knowledge workers have always had the equivalent of raw inputs – customer data, market signals, internal reports, meeting notes. What they have lacked is a factory to process them.
That’s changing.
The Knowledge Work Problem
Most of us do more repetitive work than we realise. Not repetitive in the mechanical sense – not copy-and-paste – but repetitive in structure. The same type of decision, the same format of report, the same pattern of analysis, week after week, deal after deal, customer after customer.
A sales professional assessing a new opportunity goes through the same mental checklist every time: Does this fit our ideal customer profile? Which of our solutions addresses their pain? What’s the competitive situation? What’s the risk? But each time, they must manually retrieve the relevant context, hold it all in their head, and produce a consistent output from scratch. The analysis might be excellent, but it’s expensive – in time, in cognitive load, and in consistency.
This is exactly the kind of problem a work factory is built to solve.
What Is a Work Factory?
A work factory is a structured local workspace – typically a folder on your desktop – that contains everything an AI agent needs to perform a specific category of work, on demand, consistently and to a high standard.
The division of labour is simple: humans set the strategy – the frameworks, the standards, the judgment calls that make work good. The AI handles the execution – the retrieval, the synthesis, the formatting, and the production. The factory is the structure that makes this division clean and repeatable.
Think of it like software design patterns. When the Gang of Four published Design Patterns in 1994, they didn’t invent new algorithms – they named and documented structures that experienced engineers had already discovered through practice. The value was the shared vocabulary and the captured expertise. A team that knows the Observer pattern or the Factory pattern can discuss architecture at a higher level, review each other’s designs, and avoid failure modes that others have already paid to discover.
Work factories do the same thing for AI-assisted knowledge work. Most people today organise their AI interactions ad-hoc – a prompt here, a skill file there, some context pasted in manually before each session. A work factory replaces that with a named, documented structure: a pattern that captures what works and makes it transferable. Two people who know the pattern can review each other’s factories and improve them, just as two engineers who know design patterns can review each other’s code.
There is one way some work factories go further than software patterns. A design pattern does not change when you apply it. But a factory built around an ongoing subject – a project, a team, a customer relationship – can accumulate institutional memory as a natural by-product of being used: run logs, research summaries, decisions recorded. Over time, the factory knows more than it did when it was first built.
It has three layers:
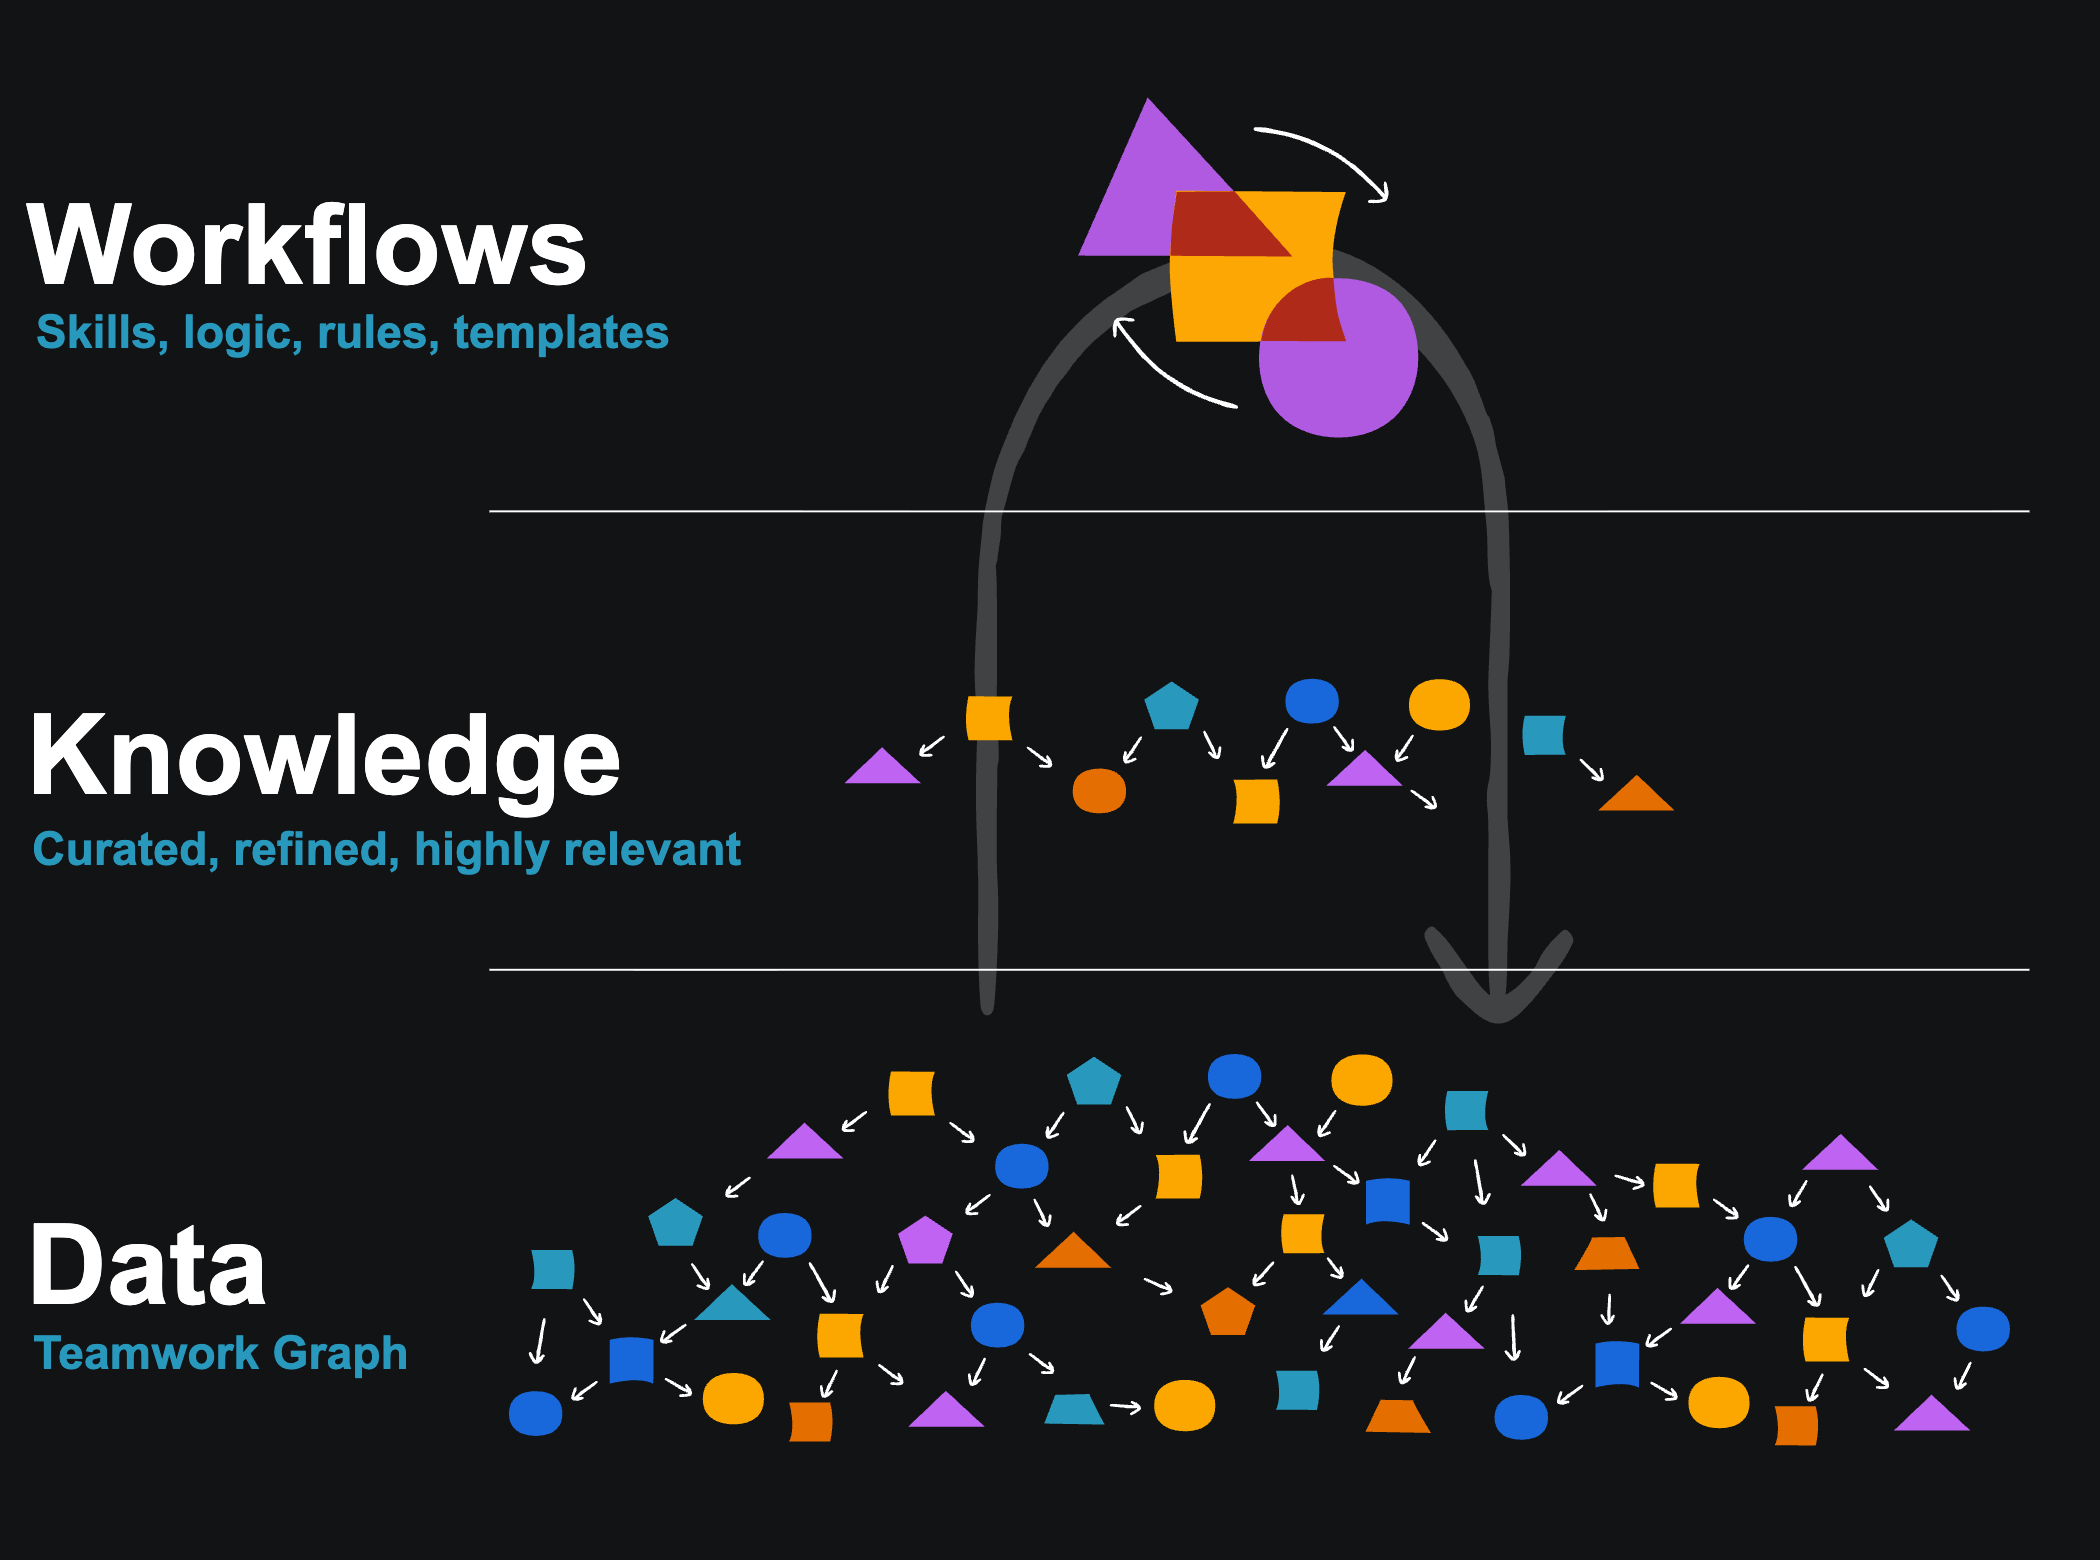
1. The Data Layer (Your Live Sources)
This is the collection of external systems the factory can search and query – Jira, Confluence, Salesforce, Google Drive, or any other connected source. Via an AI tool connected to MCP (Model Context Protocol) servers, the agent can reach into these systems to find relevant information, filter it, and use it to build or update the factory’s knowledge layer.
The key insight here is selectivity. Rather than handing the AI access to your entire company’s data estate, the factory is configured to query only the specific systems relevant to this particular type of work. That focused scope is not a limitation – it’s a feature. It reduces noise, prevents confabulations from unrelated information, and keeps the AI’s attention precisely where it needs to be.
2. The Knowledge Layer (Your Local Context)
This is where curated information about the problem domain lives – the background material that grounds the AI in your subject matter before it starts work. Think of it as answering a single question: what does the AI need to know about this domain to do the job well?
A factory’s knowledge/ directory might contain:
- Research notes – findings and sources gathered in preparation for a run
- Evergreen context – stable facts that apply to every run: key stakeholders, important dates, background on a project or product area
- Run logs – an append-only record of what was produced each run, what sources were consulted, and what changed – so the AI can detect patterns and avoid repeating itself over time
How knowledge files are managed varies by factory: some use run-scoped knowledge (each run has its own research directory, relevant only to that topic), others use evergreen knowledge (reference material that applies to every run and is kept current), and some use a mix of both.
Crucially, the knowledge/ directory is not just human-authored – the AI agent can write to it too. A workflow might instruct the agent to save a research summary, log the outcome of a run, or record a decision. Over multiple runs, the directory grows into a genuine store of institutional memory: what was found last time, what changed, what context is stable enough to reuse.
The other local files – scoring criteria, judgment rules, output templates, and process steps – live in their own directories (frameworks/, templates/, workflows/). The knowledge layer is purely informational: it tells the AI about the world, not about what to do.
3. The Skills Layer (Your AI Playbooks)
The most powerful layer is a set of AI skills – structured instruction documents that tell the AI exactly how to perform a specific task within this factory.
A skill might say: “When asked to assess an opportunity, follow these steps: first retrieve the account details from Salesforce, then retrieve the product roadmap from Confluence, then apply the scoring framework in solution-framework.md, then produce the output in the format specified in deal-brief-template.md.”
Skills turn the AI from a general-purpose assistant into a domain expert that follows your process. They encode the tribal knowledge of your best performers and make it accessible to everyone.
Many AI tools look for skills in a standard location – typically an .agents/skills/{skill-name}/SKILL.md file – so they can be discovered and invoked by name. A good pattern is to keep a thin SKILL.md file in this standard location that briefly describes the skill and points to the full skill detail inside the factory. This keeps the factory self-contained and portable while still making its skills discoverable. If the factory moves, only the pointer needs updating.
More Than Just Skills and MCP
If you’re already familiar with AI skill files or MCP server connections, you might wonder: is a work factory anything more than a collection of those things used together?
The answer is yes – but the difference is structural rather than technical.
AI skills and MCP connections are powerful primitives. Used ad hoc, they can help you accomplish individual tasks faster. But ad hoc use has limits: the skill you wrote last month may no longer match your current process, the data source you connected may return more than you need, and the output format you’re getting may drift from what your stakeholders expect. Without structure, these tools require constant re-configuration and produce inconsistent results.
A work factory adds three things that ad hoc use cannot:
1. Intentional scoping. A factory is designed for a specific job. Its data connections, knowledge files, and skills are all chosen to serve that job and nothing else. This focus is what keeps the AI’s context clean and its outputs reliable. A single loosely-configured workspace with many skills and broad data access is the worst of both worlds – too much noise for the AI, and too much maintenance for you.
2. A feedback loop. Because the factory has defined inputs, a defined process (the skill), and a defined output (the template), you can tell immediately when something isn’t working and know exactly where to fix it. Is the scoring wrong? Update the framework. Is the output format off? Update the template. Is the AI missing data? Update the data source. The factory makes improvement systematic rather than guesswork.
In short: skills and MCP give you capability. A work factory gives you a repeatable, improvable process built on top of that capability. The factory is the discipline that turns powerful tools into reliable operations.
A Realistic Example: The Sales Factory
Let’s make this concrete with a use case that illustrates all three layers in action.
The scenario: A sales professional at a mid-market software company needs to (a) assess new opportunities against a structured solution framework, and (b) produce a weekly pipeline report for their sales manager.
Without a work factory, this might take three to four hours a week – pulling data from CRM, reviewing notes, applying judgment, and writing up the outputs.
With a work factory, the same output takes minutes.
Setting Up the Factory
The sales professional creates a local folder – their Sales Factory workspace – and connects their AI tool (e.g., Claude Desktop) to relevant MCP servers:
- CRM MCP – for live opportunity data, account history, and contact notes
- Atlassian MCP – for product documentation, release notes, and internal case studies in Confluence
- Google Drive MCP – for proposal templates and past deal analyses
Into this folder, they also add their curated local knowledge files:
sales-factory/
├── skills/
│   ├── opportunity-assessment.md  ← AI skill: step-by-step assessment process
│   └── weekly-pipeline-report.md  ← AI skill: how to generate the weekly report
├── frameworks/
│   ├── solution-framework.md      ← The team's proprietary scoring methodology
│   └── ideal-customer-profile.md  ← ICP criteria and red flags
├── knowledge/
│   └── market-context.md          ← Evergreen: competitor notes, market context - refresh periodically
└── templates/
    ├── deal-brief-template.md      ← Output format for opportunity assessments
    └── pipeline-report-template.md ← Format for the weekly report
The skill files are plain text documents that the AI reads as instructions. Keeping skills, frameworks, and templates in separate files is a deliberate choice: it means you can update the output format without touching the skill logic, and templates can be shared across multiple skills as the factory grows.
Here’s an example of what opportunity-assessment.md might look like:
skills/opportunity-assessment.md
# Skill: Opportunity Assessment

## Purpose
Assess a named sales opportunity against the team solution framework and produce a completed deal brief.

## Steps
1. Ask the user for the opportunity name if not provided.
2. Retrieve the opportunity record from the CRM, including: stage, deal size, close date, contacts, and all notes.
3. Retrieve relevant product capability pages from Confluence to understand current feature availability.
4. Load and apply the scoring criteria in frameworks/solution-framework.md and frameworks/ideal-customer-profile.md.
5. Score the opportunity against each dimension of the framework on a scale of 1-10, with brief justification for each score.
6. Calculate an overall score and produce a recommended next action.
7. Format the output using the structure defined in templates/deal-brief-template.md.
8. Do not invent data. If information is missing from the CRM or Confluence, note it as "unknown" in the brief.

## Output
A completed deal brief, ready to save or share.
And a shorter example for weekly-pipeline-report.md:
skills/weekly-pipeline-report.md
# Skill: Weekly Pipeline Report

## Purpose
Generate a weekly pipeline summary covering the last 7 days of opportunity activity.

## Steps
1. Retrieve all opportunities that changed stage, value, or close date in the past 7 days.
2. Identify any deals flagged as at-risk or past their expected close date.
3. Summarise key movements: deals advanced, deals slipped, new deals added, deals lost.
4. Highlight the top 3 opportunities requiring action in the coming week.
5. Format the output using templates/pipeline-report-template.md.

## Output
A weekly pipeline report, ready to share with the sales manager.
Running the Factory: Opportunity Assessment
When a new opportunity arrives in the CRM, the sales professional opens their AI tool and says:
“Assess the Acme Corp opportunity against our solution framework.”
The AI – guided by the assess-opportunity.md skill – knows exactly what to do:
- Retrieves the Acme Corp opportunity record from the CRM (stage, deal size, contacts, notes)
- Retrieves the relevant product documentation from Confluence to understand current capabilities
- Loads the
solution-framework.mdandideal-customer-profile.mdfrom the local knowledge layer - Scores the opportunity against each dimension of the framework
- Produces a completed deal brief in the format specified by
deal-brief-template.md
The output might look like this:
Deal Brief: Acme Corp
Generated: 11 Aug 2026 | Framework: Enterprise Solution Fit v3.2
| Dimension | Score | Notes |
|---|---|---|
| ICP Fit | 8/10 | Mid-market SaaS, 500-1000 employees – strong match |
| Problem-Solution Fit | 9/10 | Their workflow automation pain directly maps to our core offering |
| Budget Alignment | 6/10 | Budget confirmed but below typical deal size – upsell path needed |
| Competitive Risk | 5/10 | Incumbent vendor entrenched – requires displacement strategy |
| Overall Score | 7/10 | Recommend: Advance to technical discovery |
Recommended next steps:
- Schedule technical discovery call to validate integration requirements
- Prepare ROI model based on their stated FTE cost ($240K/year manual process)
- Engage pre-sales for competitive positioning against incumbent
This brief is ready to share, save to the CRM, or attach to a Jira ticket. The sales professional reviews it, makes any adjustments based on nuance the data didn’t capture, and moves on.
Total time: under five minutes.
Running the Factory: Weekly Pipeline Report
Every Friday afternoon, the sales professional runs their second factory job:
“Generate my weekly pipeline report for the last 7 days.”
The AI – this time guided by the weekly-pipeline-report.md skill – knows to:
- Retrieve all opportunities that changed stage, value, or close date in the past week
- Retrieve any at-risk deals (flagged in CRM or past their expected close date)
- Load the
pipeline-report-template.mdto understand the expected output format - Draft the complete weekly report with key movements, risks, and a recommended focus for next week
The output follows the same format every week – the same sections, the same tone, the same level of detail – because the template and skill enforce it. A manager receiving this report week after week builds genuine confidence in it, because it’s predictable and consistent.
Why This Works: The Grounding Effect
The reason a work factory produces reliably good outputs is grounding. AI models are generalists – they have broad knowledge but no knowledge of your business. Left to their own devices, they produce plausible-sounding outputs that may not align with your methodology, your terminology, or your standards.
Local context changes this. When the AI has access to your solution framework, your internal processes, your output templates, and your skills – it’s no longer a generalist. For the duration of that task, it behaves like an expert who has deeply absorbed your way of working.
This is the same principle behind Retrieval-Augmented Generation (RAG) in enterprise AI systems, but applied at an individual or team level, without requiring a data engineering team to set it up.
The Periodic Work Pattern
Even used on an ad-hoc basis – assessing an opportunity as it arrives, generating a report on demand – a work factory delivers significant time savings and produces more consistent, thorough outputs than starting from scratch each time. When the same job recurs on a schedule, the value compounds even further.
Periodic tasks – weekly reports, monthly reviews, quarterly assessments, annual audits – are ideal candidates because:
- The structure is known in advance. The output format doesn’t change, so templates are stable.
- The process is well-understood. Skills can be written once and refined over time.
- Consistency has real value. Stakeholders receiving the same structure every period can focus on the content, not the format.
- Improvement compounds. Every time you refine a skill file or update a framework, every future run benefits.
Making this work in practice requires a trigger. The simplest approach is a calendar reminder that prompts you to open your AI tool and run the factory job – low-tech but effective. Some AI tools, including Claude Desktop, have built-in scheduling capabilities that can invoke a job automatically at a set time. More sophisticated setups use external scheduling tools (such as cron jobs, automation platforms like Zapier or Make, or AI agent orchestration frameworks) to invoke the factory and deliver the output to a Slack channel, email, or document. The right approach depends on how mature the factory is: start with a manual trigger while you refine the skill and framework, then automate once the output quality is consistently high enough to need only a light review.
Over time, a work factory doesn’t just save time – it becomes a capability asset. It encodes the judgment of your best performers, enforces your standards, and onboards new team members faster because the process is written down and executable.
Getting Started
You don’t need to build the full factory at once. Start with one high-frequency, structured task that you do repeatedly:
- Pick one job. Choose a task you do at least weekly that has a consistent input and output.
- Write the skill file first. Document the steps you follow, the data you need, and the format you produce. This is the most valuable thing you can create – even before the AI runs it.
- Add one data source. Connect your AI tool to the single most important external system for this task via an MCP server.
- Add your framework. Drop in the key document that encodes your judgment – a scoring rubric, a criteria checklist, an output template.
- Run it. Ask the AI to perform the task. Review the output. Refine the skill file.
- Improve the factory, not the output. If the output needs significant changes, resist the temptation to fix the artifact manually. Instead, update the skill file, framework, or template so the next run produces a better result automatically. Spending time tweaking individual outputs is an antipattern – it means the factory isn’t learning. The goal is for improvements to compound across every future run.
After two or three iterations, the quality of the output typically reaches the point where you’re making light editorial adjustments, not rewrites. That’s the factory operating at capacity. If you find yourself making the same edit repeatedly, that’s a signal to update the factory itself.
Once your first factory is running well, you can build more – one per recurring job type. A sales professional might end up with separate factories for opportunity assessment, account planning, and competitive research. Keeping them separate is intentional: a focused factory with a tight skill, a relevant framework, and a specific data source produces far better results than a single catch-all workspace. Combining everything into one place forces the AI to work with a much larger and noisier context, which dilutes its focus and degrades the quality of its outputs.
The Bigger Picture
Individual work factories, built and refined by practitioners who understand their own domain, represent a fundamentally different relationship between humans and AI. Instead of asking AI to be smarter, we are making ourselves more articulable – forcing us to write down the expertise that previously lived only in our heads.
That written expertise – the frameworks, the skills, the templates – has value beyond any single AI session. It becomes training material, onboarding documentation, a quality standard, and a shared language for the team.
The work factory doesn’t replace the knowledge worker. It amplifies them – turning a single expert’s judgment into a repeatable, scalable process that the whole team can run.
That’s the factory thinking applied to knowledge work. And it’s available today, with the tools you already have.
The patterns described in this article apply to any AI tool that supports local context and MCP server connections, including Claude Desktop, Cursor, and other MCP-compatible clients. The Atlassian Rovo MCP Server provides connectivity to Jira, Confluence, JSM, Bitbucket, and other Atlassian apps.


